Nvidia's AI Chip Dominance: What $43 Billion Profit Means for Devs
Nvidia's AI Chip Dominance: What $43 Billion Profit Means for Developers Nvidia's recent announcement of a staggering $43 billion in quarterly profit, primarily fueled by robust A.I. chip sales, isn't just a headline
Nvidia's AI Chip Dominance: What $43 Billion Profit Means for Developers
Nvidia's recent announcement of a staggering $43 billion in quarterly profit, primarily fueled by robust A.I. chip sales, isn't just a headline for financial analysts; it's a profound signal for the entire software development community. For those of us building the next generation of applications, this figure underscores a critical shift: the deep integration of specialized hardware in the modern AI stack, and the immense value being generated by technologies that leverage parallel processing at scale. This article will delve into the technical underpinnings of why GPUs are so critical for AI, how developers interact with this ecosystem, and what this financial milestone implies for our craft.
The AI Revolution and the Hardware Imperative
The explosion of artificial intelligence, particularly in areas like deep learning, large language models (LLMs), and computer vision, has created an insatiable demand for computational power far beyond what traditional CPUs can efficiently provide. The core problem is parallelism. Training a neural network involves billions, sometimes trillions, of floating-point operations (FLOPs) that can often be performed simultaneously. A CPU, optimized for sequential processing and low-latency task switching, struggles with this inherently parallel workload. Its architecture prioritizes strong, complex individual cores, but typically offers a limited number of them.
Enter the Graphics Processing Unit (GPU). Initially designed for rendering complex 3D graphics, GPUs are built with thousands of smaller, more specialized cores. Their architecture is fundamentally geared towards throughput – performing many simple calculations concurrently. This design perfectly aligns with the mathematical operations at the heart of AI, such as matrix multiplications and convolutions, which are highly parallelizable. The shift from a general-purpose computing paradigm to one heavily reliant on specialized accelerators is the primary driver behind Nvidia's unprecedented success.
Under the Hood: Why GPUs Excel at AI Workloads
To understand the technical advantage, consider the nature of deep learning. Neural networks are composed of layers of interconnected nodes, where data flows through, undergoes transformations, and updates weights during training. Each of these transformations, particularly matrix multiplications (dot products) and element-wise operations, can be broken down into many independent, identical calculations. This is where the GPU shines.
Modern Nvidia GPUs, especially those in their data center-focused 'Hopper' or 'Ampere' architectures, feature key components that accelerate AI:
- CUDA Cores: These are the basic processing units, designed for general-purpose parallel computation.
- Tensor Cores: Introduced specifically for AI workloads, Tensor Cores are specialized hardware accelerators that efficiently perform mixed-precision matrix operations (e.g., FP16 input, FP32 accumulation). This significantly speeds up operations common in deep learning, allowing for faster training and inference with reduced memory bandwidth requirements.
- High Bandwidth Memory (HBM): AI models often have billions of parameters, requiring vast amounts of data to be moved between the processing units and memory. HBM provides significantly higher memory bandwidth than traditional GDDR memory, reducing bottlenecks and keeping the Tensor Cores fed with data.
- NVLink: This is Nvidia's high-speed interconnect technology that allows multiple GPUs to communicate with each other much faster than PCIe, enabling the creation of powerful multi-GPU systems for training massive models.
The synergy of these components allows GPUs to process data for AI models orders of magnitude faster than CPUs, making large-scale AI research and deployment economically feasible.
The CUDA Ecosystem: Bridging Hardware and High-Level Development
Nvidia's dominance isn't solely due to its hardware; it's equally about its comprehensive software ecosystem, primarily CUDA (Compute Unified Device Architecture). CUDA is a parallel computing platform and programming model that allows developers to write programs that harness the power of Nvidia GPUs. It provides a C/C++ based API, a compiler, and runtime libraries, acting as the critical bridge between raw GPU silicon and high-level AI frameworks.
For developers, CUDA abstracts away much of the complexity of GPU programming. While direct CUDA programming offers maximum control and optimization, most AI practitioners interact with the ecosystem through higher-level frameworks like TensorFlow and PyTorch. These frameworks, along with libraries such as cuDNN (CUDA Deep Neural Network library) and cuBLAS (CUDA Basic Linear Algebra Subprograms), are heavily optimized to leverage CUDA-enabled GPUs. When you define a neural network layer or an optimizer in PyTorch, the underlying operations are often compiled down to highly optimized CUDA kernels that execute efficiently on Nvidia hardware.
This robust and mature software stack has created a strong vendor lock-in, as alternative accelerators (like AMD's ROCm or Intel's oneAPI) are still catching up in terms of feature completeness, community support, and ease of use. The ease of developing and deploying on Nvidia's platform is a significant factor in their market leadership.
Scaling AI: From Training to Inference
The need for specialized hardware spans both the training and inference phases of the AI lifecycle. Training large, complex models can take days or weeks even on clusters of top-tier GPUs. Companies are deploying hundreds or thousands of these specialized chips in data centers to handle the massive computational demands of pre-training foundational models or fine-tuning highly specific ones. Nvidia's profit figure directly reflects this infrastructure build-out.
Once a model is trained, inference (making predictions with the model) also benefits from GPU acceleration, especially for real-time applications or high-throughput scenarios. While some inference can be pushed to CPUs or specialized edge devices, for demanding tasks like real-time video analysis, large-scale language generation, or high-volume prediction services, GPUs offer unmatched speed and efficiency. This bifurcation of compute needs – intense training followed by efficient, scalable inference – means a continuous demand for both high-end and optimized GPUs.
Performance Considerations and Hardware Trade-offs
While GPUs offer unparalleled performance for AI, developers must be acutely aware of the associated trade-offs:
- Cost: High-end data center GPUs are incredibly expensive, contributing significantly to cloud computing costs or on-premise infrastructure investments. This cost impacts budgeting for AI projects and influences architectural decisions.
- Power Consumption: These chips are power-hungry, requiring robust cooling solutions and substantial energy. This has environmental implications and adds to operational expenses.
- Memory Bandwidth vs. Capacity: While HBM provides immense bandwidth, the total memory capacity on a single GPU (e.g., 80GB on an H100) can still be a limiting factor for truly colossal models or large batch sizes. Distributed training across multiple GPUs becomes essential.
- Programming Complexity: While frameworks abstract much away, optimizing for GPU performance still requires understanding concepts like memory coalescing, kernel launch configurations, and potential bottlenecks. Debugging GPU code can also be more challenging than CPU code.
Understanding these factors is crucial for designing efficient, cost-effective, and scalable AI solutions. Simply throwing more hardware at a problem without optimization can lead to prohibitive costs and diminishing returns.
Practical Takeaways for Developers
Nvidia's financial success is a clear indicator of the direction the industry is heading. For developers, this translates into several practical considerations:
- Embrace Parallel Programming Concepts: Even if you're working with high-level frameworks, a fundamental understanding of parallel processing, memory hierarchies, and asynchronous operations will make you a more effective AI developer.
- Deepen Your AI Framework Knowledge: Understanding how TensorFlow, PyTorch, or JAX leverage underlying hardware and knowing optimization techniques (e.g., mixed-precision training, distributed training strategies) is no longer optional.
- Consider MLOps and Infrastructure: As AI models become larger and more complex, the role of MLOps – managing the lifecycle of machine learning models, including deployment, monitoring, and scaling – becomes paramount. This includes understanding the infrastructure needed to support GPU-intensive workloads.
- Stay Aware of Hardware Evolution: The pace of innovation in AI accelerators is rapid. Keeping an eye on new GPU architectures, specialized AI ASICs, and interconnect technologies will inform future design choices and potential performance gains.
- Cost-Aware Development: Given the high cost of GPU compute, writing efficient code, choosing appropriate model sizes, and optimizing training/inference pipelines can lead to significant cost savings.
Nvidia's $43 billion profit isn't just a number; it's a testament to the monumental shift towards specialized hardware-accelerated computing driven by AI. For developers, it's a call to action to deepen our understanding of this critical layer of the tech stack and to build the future of intelligent applications on a foundation of powerful, parallel computation.
Q: How does a GPU handle data compared to a CPU for AI tasks?
A: A CPU processes data sequentially with powerful, complex cores optimized for single-thread performance and diverse tasks. A GPU, conversely, employs thousands of simpler, specialized cores to process many data points simultaneously in parallel. For AI, where operations like matrix multiplication can be broken down into numerous independent calculations, the GPU's parallel architecture is far more efficient at achieving high throughput.
Q: What is CUDA's role in Nvidia's AI dominance?
A: CUDA is Nvidia's proprietary parallel computing platform and programming model. It provides the software interface that allows developers and high-level AI frameworks (like PyTorch and TensorFlow) to harness the power of Nvidia GPUs. Its maturity, extensive libraries (cuDNN, cuBLAS), and broad developer adoption have created a robust ecosystem, making it significantly easier to develop and deploy AI solutions on Nvidia hardware, thereby solidifying their market position.
Q: Beyond raw computational power, what other factors make high-end GPUs essential for large AI models?
A: Beyond raw FLOPs, high-end GPUs are essential due to High Bandwidth Memory (HBM), which provides significantly faster data transfer rates to keep the processing units supplied. They also feature specialized hardware like Tensor Cores for efficient mixed-precision operations and high-speed interconnects like NVLink for scaling training across multiple GPUs. These elements collectively address the memory bandwidth, data transfer, and specialized operation needs of large AI models, which are often bottlenecks on less specialized hardware.
Related articles

AI's Confidence vs. Formal Methods' Rigor: Design Flaws & Verification
While AI accelerates code generation, formal methods remain critical for ensuring system correctness. Languages like TLA+ and tools like Quint enable developers to model and verify system designs before coding, catching subtle flaws. Quint makes formal methods more accessible with developer-friendly syntax and executability. This approach is vital for verifying AI-generated code through trace validation and model-based testing, ensuring reliability against real-world data.
regional: A two-person Seattle startup lands $1M to reinvent
Seattle startup TriMagnetix has secured $1 million to develop semiconductor chips that consume 800 times less energy and are radiation-resistant. The two-person company, leveraging nanomagnetic technology, is targeting space applications and data centers. With new funding and key partnerships, TriMagnetix aims for commercial sales within a year.

Ephemeral PR Preview Environments on GKE: A Deep Dive
Every development team eventually grapples with the limitations of shared staging environments. The familiar scenario: multiple features deployed simultaneously, database migrations clashing, and the phrase "it works on
Enterprise AI Beyond Chatbots: A Vision for Actionable Intelligence
Quick Verdict: Redefining Enterprise AI's Potential TechRadar Pro's opinion piece, "What it takes to move enterprise AI beyond the chatbot," delivers a refreshingly honest and vital perspective on the current state and

Secure Internal API Access for AI Agents with MCP
AI agents accessing internal APIs directly pose significant risks, including identity loss, unrestricted queries, and security bypasses. The Model Context Protocol (MCP) offers a solution by defining explicit tools. A secure architecture involves an MCP server wrapping the API with strict input validation, coupled with a gateway that handles authentication, rate limiting, and audit logging, ensuring safe and accountable access.
regional: ‘What is fusion?’ Helion Energy harnesses the power of
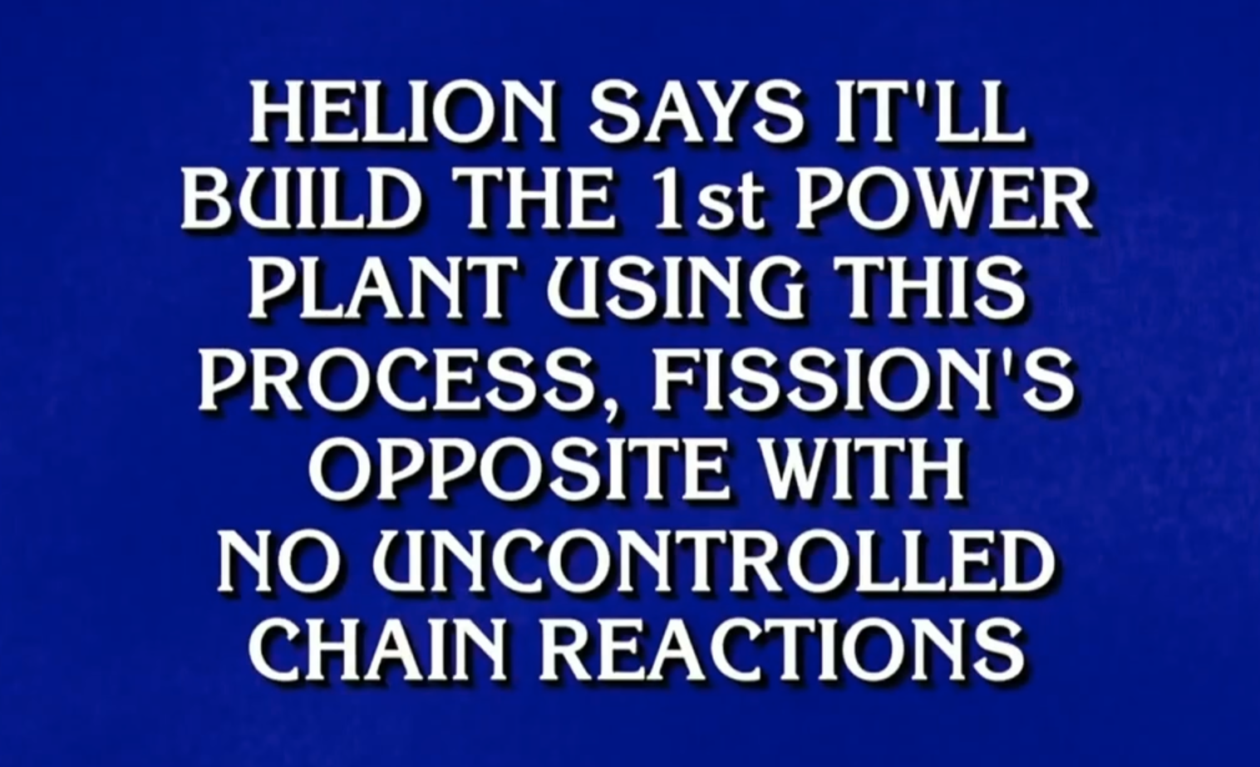
Helion Energy, the Everett-based fusion startup, gained mainstream attention this week after being featured as a clue on the popular game show "Jeopardy!". The $800 clue, part of a "Y Combinator" category, highlighted Helion's mission to build the first fusion power plant, bringing the concept of clean energy to a wider audience. CEO David Kirtley celebrated the "surreal" moment as a sign that reliable clean power is becoming more accessible.