Graph-Enhanced RAG: Beyond Vector Search for Enterprise Data
Graph-Enhanced RAG: Solving LLM Context Gaps in Production In a significant evolution for large language model (LLM) deployment, a new architectural pattern is emerging that promises to resolve critical context
Graph-Enhanced RAG: Solving LLM Context Gaps in Production
In a significant evolution for large language model (LLM) deployment, a new architectural pattern is emerging that promises to resolve critical context limitations inherent in traditional retrieval-augmented generation (RAG) systems. Introduced by Daulet Amirkhanov on VentureBeat, this "graph-enhanced RAG" approach moves beyond simple vector search to provide LLMs with a deeper, structural understanding of enterprise data, particularly in complex, interconnected domains.
Traditional RAG, which relies on chunking documents, embedding them into vector databases, and retrieving top-k results via semantic similarity, has become a standard for grounding LLMs in private data. While effective for unstructured semantic search, this vector-only method often falls short when dealing with highly interconnected enterprise data, such as supply chains, financial compliance, or fraud detection. The core issue, as highlighted by Amirkhanov, is that vector search captures similarity but frequently misses structure.
The Limitations of Vector-Only Retrieval
Vector databases excel at identifying meaning within text but can inadvertently discard crucial topological relationships. When documents are broken into chunks and embedded, explicit connections like hierarchy, dependency, or ownership are often flattened or lost. This deficiency becomes apparent when LLMs face multi-hop reasoning questions, such as understanding how a delay in one component might impact a specific client's deliverable.
Consider a hypothetical supply chain scenario: a SQL database explicitly links Supplier A to Component X and Factory Y, while an unstructured news report details flooding at Supplier A's facility. A standard vector search might retrieve the news report due to semantic relevance to "production risks." However, without an explicit structural link, the LLM struggles to connect this event directly to Factory Y's output. This often leads to LLMs either hallucinating relationships or failing to answer critical business questions despite the relevant data existing within the system.
Introducing Hybrid Graph-Enhanced RAG
To overcome these challenges, the proposed solution is a "Graph RAG" architecture, built on a three-layer stack designed to integrate semantic flexibility with structural determinism:
- Ingestion: Drawing from experience at Meta, Amirkhanov emphasizes enforcing structure early. During ingestion, entities (nodes) and relationships (edges) are extracted from text chunks, often using LLMs or Named Entity Recognition (NER) models, and linked to an existing graph database. This ensures structural integrity from the outset.
- Storage: A graph database, such as Neo4j, stores the intricate structural graph. Vector embeddings, which capture semantic meaning, are then stored as properties directly on specific nodes within this graph, like a 'RiskEvent' node.
- Retrieval: This layer executes a hybrid query. It begins with a vector scan to identify initial entry points in the graph based on semantic similarity. Following this, it performs a graph traversal, navigating relationships from those entry points to gather comprehensive contextual information.
A Practical Supply Chain Example
Amirkhanov illustrates this pattern with a simplified supply chain risk analyzer. After modeling the graph to connect risk events with structured supply chain entities, a new unstructured risk event, like a news report about flooding, is ingested. This event is not just embedded; it's linked to the relevant supplier in the graph.
The critical difference lies in the hybrid retrieval query. Instead of merely returning a generic text chunk, the system uses a Cypher query to combine vector search for the event with graph traversal to identify downstream impacts. The LLM then receives a structured payload, clearly outlining the issue, the impacted supplier, and the specific factory at risk. This enables the LLM to generate precise, grounded answers like, "The flooding at TechChip Inc puts Assembly Plant Alpha at risk," rather than vague or inaccurate responses.
Navigating Production Challenges
Implementing graph-enhanced RAG in production introduces new considerations, particularly around latency and data consistency.
Graph traversals are inherently more resource-intensive than simple vector lookups, potentially increasing retrieval times from ~50-100ms for vector-only RAG to ~200-500ms for graph-enhanced RAG. To mitigate this "latency tax," semantic caching is employed. If a new query is semantically similar to a previous one (e.g., cosine similarity > 0.85), the cached graph result is served, reducing the need for repeated complex traversals.
Another challenge is the "stale edge" problem. Unlike independent vector data, graph data is highly interdependent. If a supplier-factory relationship changes but the graph isn't updated, the system could confidently provide incorrect information. This is addressed by implementing Time-To-Live (TTL) for graph relationships or integrating Change Data Capture (CDC) pipelines that sync graph data with authoritative source systems, such as an ERP.
Deciding on Graph-Enhanced RAG
The decision to adopt graph-enhanced RAG depends on specific use cases and requirements:
- Vector-only RAG remains suitable if: The data corpus is relatively flat (e.g., a chaotic wiki or chat logs), questions are broad (e.g., "How do I reset my VPN?"), or latency below 200ms is a strict necessity.
- Graph-enhanced RAG is recommended if: The domain is regulated (e.g., finance, healthcare) requiring explainability, the answer necessitates multi-hop relationships (e.g., "Which indirect subsidiaries are affected?"), or a clear traversal path for reasoning is crucial.
Conclusion
Graph-enhanced RAG represents a crucial advancement for LLMs operating in complex enterprise environments. By treating underlying infrastructure as a sophisticated knowledge graph, organizations can provide their LLMs with the explicit structural truth of their business. This integrated approach ensures richer context and more accurate, explainable responses, moving LLM grounding beyond mere semantic similarity to encompass the full topology of critical business data.
FAQ
Q: What is the primary limitation of vector-only RAG for enterprise data?
A: Vector-only RAG excels at semantic similarity but often discards topological relationships and explicit structural context, making it difficult for LLMs to perform multi-hop reasoning or understand dependencies within complex enterprise data.
Q: How does graph-enhanced RAG address multi-hop reasoning?
A: Graph-enhanced RAG addresses multi-hop reasoning by combining an initial vector scan to find semantic entry points with subsequent graph traversals. This allows the system to navigate explicit relationships (edges) between entities (nodes) to gather comprehensive contextual information that spans multiple data points.
Q: What are key considerations when implementing graph-enhanced RAG in production?
A: Key production considerations include managing increased latency due to graph traversals, often mitigated by semantic caching, and addressing the "stale edge" problem to ensure data consistency. This requires implementing Time-To-Live (TTL) for relationships or syncing graph data via Change Data Capture (CDC) pipelines from authoritative sources.
Related articles

Apple Unveils iPhone Duo: Pricey Foldable Sees Soaring Demand
Apple has officially entered the foldable smartphone arena with the long-anticipated launch of the iPhone Duo. Priced starting at a hefty $1,999, the device features a 5.4-inch outer display and a larger 7.6-inch inner

in-depth: Chicago-Area Cops Helped HSI Spy on Minnesota Anti-ICE
Chicago-area law enforcement, including local police and HSI agents, conducted undercover surveillance on Minnesota anti-ICE activists at an April 2, 2022, talk in Chicago. This operation was part of a federal conspiracy probe into 15 Minnesota activists facing felony charges related to immigration enforcement resistance. Civil liberties advocates have condemned the surveillance as a troubling intrusion into protected political activity.
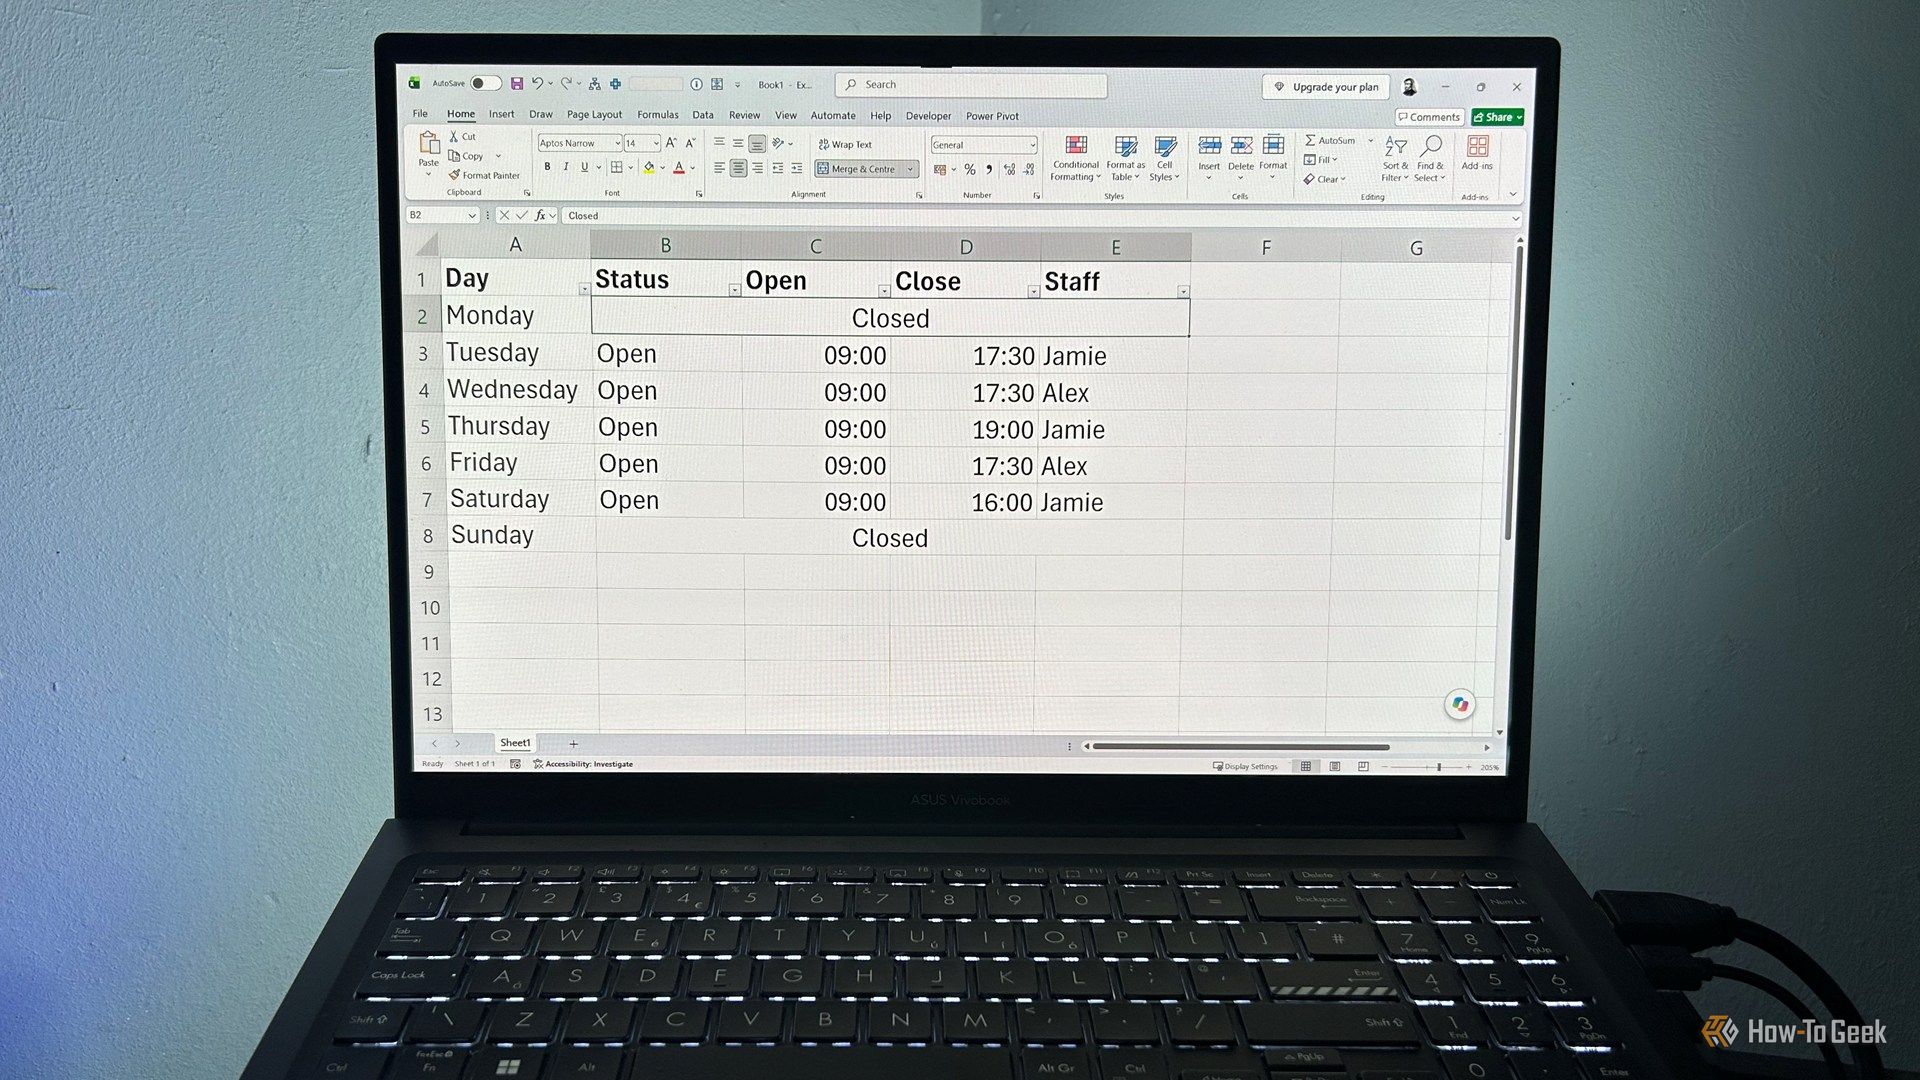
Ditch Merge & Center: The Better Way to Align Text in Excel
Learn to use Excel's "Center Across Selection" to align text across cells without merging, avoiding common data manipulation issues. This guide provides steps to utilize this newly accessible feature and add it to your Quick Access Toolbar.

Mark Wahlberg on using AI in film ‘the right way’ and being open to
Actor Mark Wahlberg believes AI has a place in filmmaking if used responsibly for enhancement, not script generation or actor replacement. At TechCrunch Disrupt, he expressed openness to an AI likeness carrying on his legacy, managed by his family, and emphasized storytelling.
Ars Technica's Rocket Report: Your Essential Space Industry Briefing
Quick Verdict Ars Technica's Rocket Report, presented by veteran space reporter Stephen Clark, offers an invaluable and meticulously organized weekly (or similar frequency, implied by "Edition 9.15") digest of the most
Tesla Unveils Thruster-Equipped Roadster, 2028 Production Targeted
Tesla has unveiled its second-generation Roadster, featuring cold-gas thrusters co-developed with SpaceX, enabling it to jump and flip. The electric sports car demonstrated 0-60mph in an astonishing 0.81 seconds, with production targeted for 2028. This highly anticipated reveal also serves as a key recruitment tool for Tesla's ambitious AI and robotics initiatives.