From Demo to Dependable: Building Production-Grade LLM Systems
The world of Large Language Models (LLMs) and autonomous agents is brimming with impressive demonstrations. We've all seen the videos: agents generating code, answering complex queries, or orchestrating tasks with
The world of Large Language Models (LLMs) and autonomous agents is brimming with impressive demonstrations. We've all seen the videos: agents generating code, answering complex queries, or orchestrating tasks with seemingly magical fluidity. But for many developers, there's a significant chasm between a captivating proof-of-concept and a robust, reliable system ready for production use, handling real customers and real money.
Crossing this divide isn't about simply using a larger, more powerful model. It's about surrounding that probabilistic core with the 'boring machinery' of solid software engineering: determinism, rigorous evaluation, calibrated confidence, layered guardrails, an immutable audit trail, and comprehensive observability. These are the unsung heroes that transform an impressive demo into a dependable application.
The Core Principle: Containing Probabilistic Models
At its heart, the challenge lies in the probabilistic nature of LLMs. Production systems, however, demand guarantees. You cannot make an LLM inherently deterministic, nor should you try. Instead, the strategy is to constrain the model's role to the smallest decision that genuinely requires its judgment. This decision is then enveloped by deterministic, testable, auditable, and observable machinery. In essence, the LLM becomes a contained component within an otherwise ordinary, well-engineered software system.
The LLM Production Maturity Model
Transitioning to production readiness is a journey best approached systematically. We can define a maturity model, where each level builds upon the foundations laid by the preceding one. Attempting to skip levels often leads to instability and unexpected failures down the line.
-
Level 0: Notebook — The Happy Path Demo
- What you have: A prompt, an LLM, and a few cherry-picked examples where it shines. It's easy to get started and showcase potential.
- The tell for gaps: "It works great on my examples!" You're likely only testing the ideal scenarios, overlooking edge cases or unintended behaviors.
-
Level 1: Determinism — Controlled Interaction
- What you have: Agents propose actions rather than directly applying changes. Capabilities are structured as fixed sequences of steps, with the model confined to specific nodes. Loops (like in ReAct patterns) are strictly bounded to prevent endless wandering.
- The tell for gaps: The agent writes directly to business state, or its behavior unpredictably changes based on the arbitrary path it took through potential actions.
-
Level 2: Evaluation — Continuous Quality Assurance
- What you have: Comprehensive evaluations integrated into your Continuous Integration (CI) pipeline, acting as a deployment gate. Baselines track performance drift, and shadow evaluations from production data provide real-world insights.
- The tell for gaps: You change a prompt or model version and merely "hope" for the best. Evaluations, if they exist, are ad-hoc scripts living in a notebook, not automated gates.
-
Level 3: Confidence — Knowing When to Abstain
- What you have: A composed, calibrated confidence score attached to each decision. A predefined threshold automatically routes low-confidence decisions to a human for review (Human-in-the-Loop). A sampled judge system verifies the accuracy of these confidence scores.
- The tell for gaps: Your system acts on raw model confidence, which can be misleading, and lacks the ability to gracefully abstain or escalate decisions when uncertain.
-
Level 4: Safety & Governance — Defense in Depth
- What you have: Layered guardrails (input, output, PII redacting, verification, human judgment) designed to fail closed. Sensitive data is redacted or hashed at the system boundary. An append-only audit ledger tracks all interactions and decisions, and memory is scoped to prevent cross-tenant data leakage.
- The tell for gaps: Reliance on a single moderation filter, raw inputs appearing in logs, or mutable audit trails that lack integrity.
-
Level 5: Operability — Running a System, Not Just a Model
- What you have: Robust observability for agent decisions, token costs, and guardrail blocks. Cost control mechanisms, intelligent model routing with fallbacks, and instantaneous kill switches allow for graceful degradation and emergency stops.
- The tell for gaps: You discover quality issues, performance bottlenecks, or unexpected costs only through customer complaints or hefty cloud invoices.
-
Level 6: Production-Grade Build — Self-Healing, Self-Improving
- What you have: The build process itself is disciplined, potentially leveraging an "operating system" for coding agents. Hard-won architectural and decision-making knowledge is captured in a decision log, readable by both humans and agents, preventing re-litigation of common issues.
- The tell for gaps: Critical system knowledge is tribal, residing only in specific developers' heads, and common decisions are re-debated every few weeks.
Are You Production-Ready? A Quick Self-Assessment
To gauge your current standing, consider these indicators:
- Does your agent system only propose changes, with a separate component responsible for applying them after approval?
- Is each agent capability a fixed sequence of steps, isolating the model to a single step?
- Does a prompt or model change that degrades quality automatically fail your CI pipeline?
- Do you compare each release against a historical performance baseline, not just a pass/fail threshold?
- Are decisions accompanied by a composed, calibrated confidence score, routing low-confidence instances to a human?
- Are your guardrails layered (input, output, PII, verify, judge) and designed to fail closed?
- Is sensitive data consistently redacted/hashed at your system's boundary, and is your audit ledger append-only?
- Can you view agent decisions, guardrail blocks, token costs, and human override rates on a centralized dashboard?
- Can you halt automated decisions within seconds without requiring a new deployment?
- Are your team's critical architectural and operational decisions documented in a structured log, accessible to both humans and agents?
If you ticked fewer than half of these, your LLM system might be earlier in its maturity journey than its impressive demos suggest. The path to production-grade LLMs is about disciplined engineering, layer by layer.
The Takeaway
Achieving production readiness for LLMs and agents isn't about blindly trusting the model more; it's about robustly containing it. It means diligently building the measurable, testable, auditable, and observable system around the probabilistic core. Climb these maturity levels in sequence, and you'll transform a fascinating experiment into a dependable, valuable product.
FAQ
Q: Why can't we simply make the LLM output deterministic for production use?
A: LLMs are inherently probabilistic by design, generating responses based on learned probability distributions. While you can reduce variability (e.g., by setting temperature to 0), true determinism isn't achievable in a way that provides guarantees for critical systems. The production-grade approach acknowledges this and instead builds a deterministic system around the LLM, shrinking the model's role to a controlled judgment task within that system.
Q: What's the biggest challenge teams face when moving an LLM demo to production?
A: The biggest challenge is often underestimating the need for robust engineering disciplines around the LLM. Demos can mask fundamental issues like lack of determinism in agent behavior, absence of objective evaluation, poor error handling, inadequate safety measures, and opaque operational visibility. Teams tend to focus on model quality rather than the surrounding system's reliability and governance.
Q: How does the concept of "shrinking the model's job" influence agent architecture?
A: Shrinking the model's job means designing your agent to delegate complex, multi-step reasoning to the LLM only for specific, well-defined decision points that require judgment. The rest of the workflow – tool selection, input validation, output parsing, state management, and orchestration – should be handled by conventional, deterministic code. This often leads to an architecture where the LLM is a function call within a larger, structured execution graph, rather than being solely responsible for the entire agentic loop.
Related articles
Accelerate UI Development: Building Interfaces with AI Prompts
Leverage AI prompts to rapidly build website user interfaces. This article explains how to craft detailed prompts for AI coding tools, utilizing `shadcn/ui`, Next.js, and Tailwind CSS to generate functional and reusable UI components. Learn to streamline your UI development workflow.
Anthropic's AI Watchdog: A Bold Step Towards Accountability
Verdict: A Meaningful Leap in AI Governance, But Not Without Caveats Anthropic's decision to grant an independent AI watchdog "employee-like" access to its internal systems is a significant move in the ongoing debate

Plug-in Solar Legalization: A Bright Step for Home Energy
The legalization of plug-in solar in 10 US states signals a major shift towards accessible home energy. This review covers the systems, legal status, savings potential, and crucial considerations for consumers.
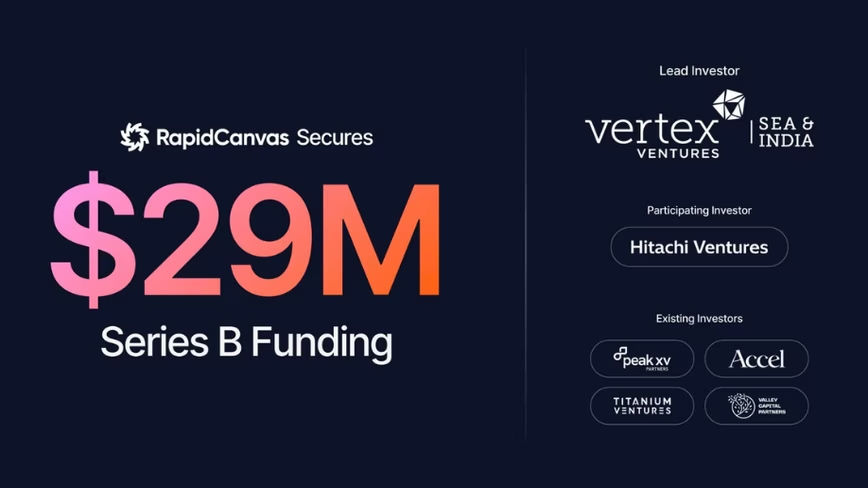
RapidCanvas Secures $29M Series B to Scale Enterprise AI Solutions
Austin, Texas – RapidCanvas, a burgeoning startup specializing in building and running custom AI applications for enterprises, has announced a successful close of its Series B funding round, raising $29 million. Led by
TCG Pocket Responds: A Much-Needed Pace Shift for Pokémon Fans
Pokémon TCG Pocket is rolling out a major update for its second anniversary, primarily addressing player concerns about overwhelming content releases by shifting to a six-week set schedule. This aims to curb player decline and improve overall engagement by giving trainers more time to collect and strategize. The update also adds new collection methods, improved deck-building features, and enhanced trading functionality.
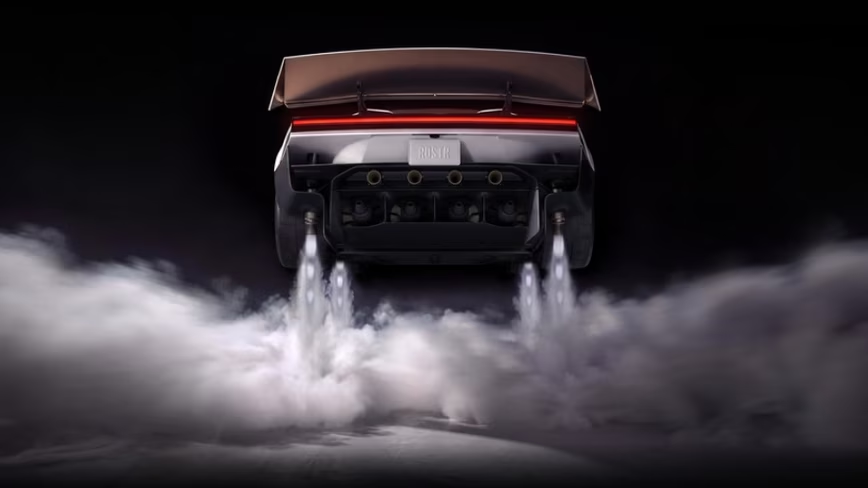
Tesla Unveils Thruster-Equipped Roadster, 2028 Production Targeted
Tesla has unveiled its second-generation Roadster, featuring cold-gas thrusters co-developed with SpaceX, enabling it to jump and flip. The electric sports car demonstrated 0-60mph in an astonishing 0.81 seconds, with production targeted for 2028. This highly anticipated reveal also serves as a key recruitment tool for Tesla's ambitious AI and robotics initiatives.