DeepSeek's 75% Price Cut: A Glimmer of Hope Dimmed by '100x Problem
DeepSeek's recent 75% price reduction for its V4-Pro model, a move that should have been unequivocally celebrated by the enterprise AI sector, is instead revealing a critical flaw in the economic model of AI agent
DeepSeek's recent 75% price reduction for its V4-Pro model, a move that should have been unequivocally celebrated by the enterprise AI sector, is instead revealing a critical flaw in the economic model of AI agent systems. While inference costs are indeed plummeting, AI agents are consuming tokens at such a voracious pace that these savings are being nullified, leading to the emergence of the '100x problem' and threatening the profitability of AI-native companies and features.
Traditionally, software economics saw infrastructure costs decrease while application capabilities grew. The initial assumption for AI was similar: as models improved and token prices dropped, inference was expected to become a negligible operating expense. However, this assumption is rapidly crumbling as multi-step AI agents, unlike single-turn chatbots, generate an exponentially higher volume of billable operations for a single user request.
The Token Amplification Challenge
A standard chatbot typically translates one user question into one model call, with an input-to-billed token ratio of about 1:5. In stark contrast, a multi-step agent — deployed across complex functions like customer support, sales, or legal review — can generate a ratio of 1:700 or higher. This occurs because each loop iteration carries forward cumulative conversation context, tool outputs, and reasoning traces, continuously appending to the billed token count.
Consider a seemingly simple agent query such as “What did our top customer ask about last week?” This single request can involve approximately seven priced operations, from the initial user prompt and system prompts to multiple model calls for tool selection, retrieval, summarization, and follow-up decisions. The result is an estimated 35,000 input tokens billed for one sentence, translating to $0.10 to $0.40 per query on a frontier model. For an enterprise handling a million queries a month, this quickly escalates to a six-figure monthly expense.
This phenomenon of 'token amplification' directly undermines the dominant seat-based SaaS pricing model for enterprise AI. When a power user's daily agent activity incurs more in inference costs than their monthly subscription fee, vendor gross margins turn negative. This paradox deepens as customer adoption increases, creating a financial headwind for companies that were banking on scaling their AI offerings. Reports from vendors increasingly show negative gross margins for heavy users, highlighting a disconnect between product value and profitability.
Nvidia's VP of Applied Deep Learning, Bryan Catanzaro, underscored this shift, stating, "For my team, the cost of compute is far beyond the costs of the employees." This statement signifies that the fundamental business model assumed by most AI-native companies is proving unsustainable under the weight of agentic workloads.
Orchestration as the New Moat
Addressing the 100x problem requires strategic technical responses focused on efficient agent orchestration. Key techniques include:
- Cost-aware routing: Utilizing smaller classifier models to direct queries to the most cost-effective model tiers, potentially cutting inference bills by around 60% without sacrificing quality.
- Prompt caching: Leveraging discounts offered by model providers (Anthropic, OpenAI, Google) for cached prefixes, yielding 75-90% savings.
- Context discipline: Actively truncating tool outputs, pruning reasoning traces, and capping tool depth to prevent agents from incurring unnecessary token consumption.
- Speculative decoding: For self-hosted deployments, this technique can significantly boost effective throughput on existing GPUs by 2 to 3 times.
Companies successfully implementing this orchestration layer are beginning to resemble financial trading systems, where every routing decision is priced, every path has its own profit and loss, and every tenant operates within a metered budget. IBM's research supports this, indicating that orchestration-led governance leads to six times greater productivity impact than compliance-only approaches.
Strategic Moves for Enterprise Leaders
To navigate this evolving landscape, enterprise leaders must:
- Prioritize inference costs: Make inference cost a first-class metric, tracking it meticulously per-feature, per-tenant, and per-query class, much like cloud costs were managed a decade ago.
- Implement media buyer-style budgeting: Establish and enforce cost-per-thousand-queries ceilings for each feature, with alerts for overruns.
- Elevate the router: Treat the routing layer as core infrastructure, akin to a load balancer, rather than a mere optimization.
- Regularly audit prompts: Quarterly reviews of production prompts are essential, as an organically growing 4,000-token system prompt can quietly accumulate significant costs.
- Negotiate volume commits: Engage with frontier-model vendors early to secure reserved-instance-style prepaid commits, which offer substantial discounts over list prices.
While DeepSeek's price cuts highlight a continuing trend of declining inference unit costs—roughly 3X per year—the core issue remains that token amplification is outpacing these reductions. A 75% price cut offers little relief if agents are consuming 700 times more tokens per user query than the pricing model accounts for. In this new era, architectural decisions are inherently financial decisions, and the survival of AI ventures hinges on developing agents that are not only intelligent but also acutely aware of their operational costs. The 100x problem is accelerating, demanding immediate and strategic responses from the industry.
FAQ
Q: What is the "100x problem" in AI? A: The "100x problem" refers to the phenomenon where AI agent systems consume tokens at a rate exponentially higher (often 100x or more, reaching 700x in some cases) than traditional chatbots for a single user-visible request, leading to dramatically increased inference costs that often negate any price cuts on token usage.
Q: How does token amplification impact existing AI business models? A: Token amplification breaks the traditional seat-based SaaS pricing model. If a power user's agent activity costs more in inference than their monthly subscription fee, vendors face negative gross margins, turning their most engaged users into unprofitable customers and undermining the very usage growth they seek.
Q: What are the key strategies to mitigate the "100x problem"? A: Mitigation strategies primarily revolve around intelligent agent orchestration, including cost-aware routing to cheaper models, leveraging prompt caching for discounts, practicing context discipline to minimize token use, and employing speculative decoding for self-hosted deployments to increase throughput.
Related articles

Apple Unveils iPhone Duo: Pricey Foldable Sees Soaring Demand
Apple has officially entered the foldable smartphone arena with the long-anticipated launch of the iPhone Duo. Priced starting at a hefty $1,999, the device features a 5.4-inch outer display and a larger 7.6-inch inner

in-depth: Chicago-Area Cops Helped HSI Spy on Minnesota Anti-ICE
Chicago-area law enforcement, including local police and HSI agents, conducted undercover surveillance on Minnesota anti-ICE activists at an April 2, 2022, talk in Chicago. This operation was part of a federal conspiracy probe into 15 Minnesota activists facing felony charges related to immigration enforcement resistance. Civil liberties advocates have condemned the surveillance as a troubling intrusion into protected political activity.

Mark Wahlberg on using AI in film ‘the right way’ and being open to
Actor Mark Wahlberg believes AI has a place in filmmaking if used responsibly for enhancement, not script generation or actor replacement. At TechCrunch Disrupt, he expressed openness to an AI likeness carrying on his legacy, managed by his family, and emphasized storytelling.
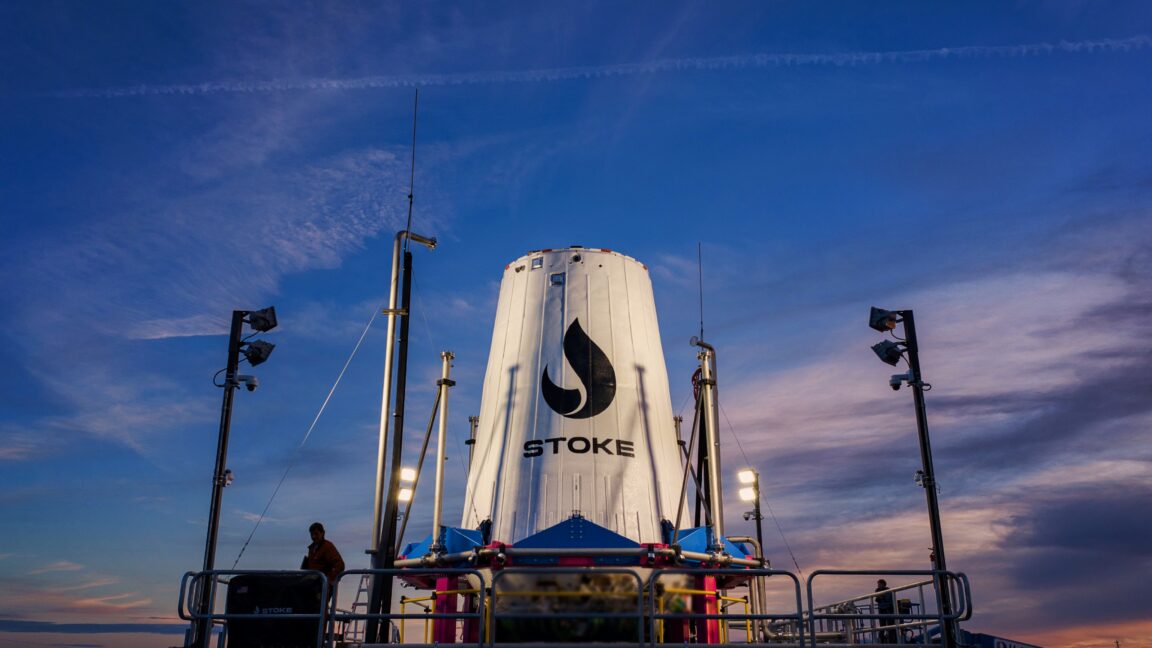
Ars Technica's Rocket Report: Your Essential Space Industry Briefing
Quick Verdict Ars Technica's Rocket Report, presented by veteran space reporter Stephen Clark, offers an invaluable and meticulously organized weekly (or similar frequency, implied by "Edition 9.15") digest of the most
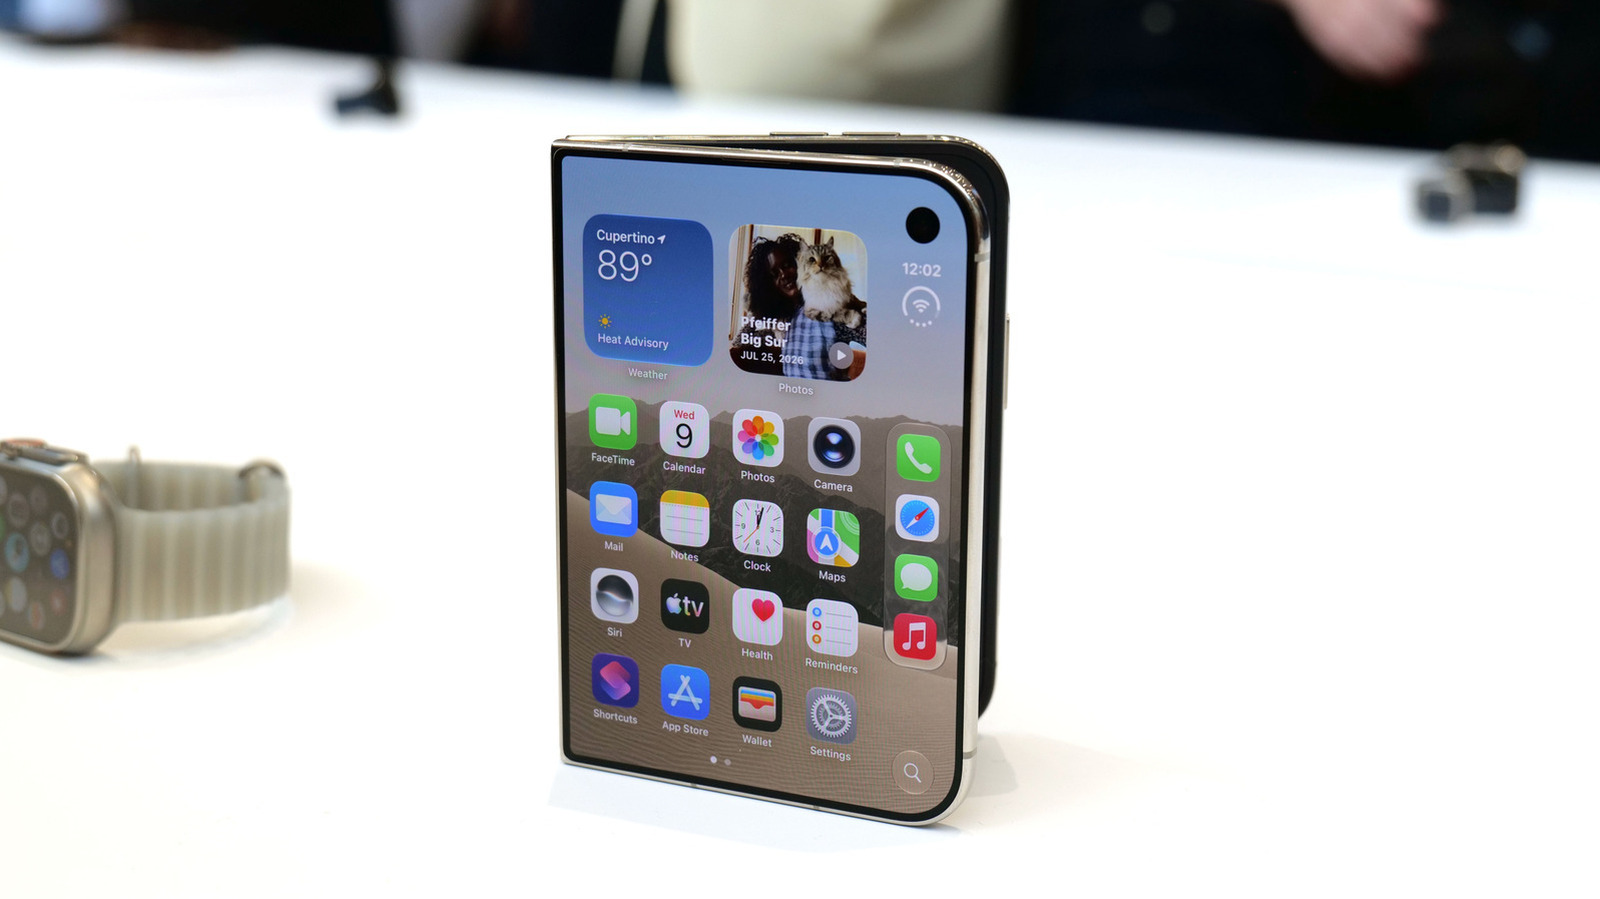
Apple iPhone Duo: A Daring Debut with Notable Compromises
Apple's highly anticipated iPhone Duo, priced at $2,000, has gone on pre-order. While hailed as "Apple's most exciting device in a decade" for its innovative foldable design and immersive display, it comes with significant drawbacks like the absence of FaceID and a premium camera.
Tesla Unveils Thruster-Equipped Roadster, 2028 Production Targeted
Tesla has unveiled its second-generation Roadster, featuring cold-gas thrusters co-developed with SpaceX, enabling it to jump and flip. The electric sports car demonstrated 0-60mph in an astonishing 0.81 seconds, with production targeted for 2028. This highly anticipated reveal also serves as a key recruitment tool for Tesla's ambitious AI and robotics initiatives.